A stock news and sentiment scoring API is not just a feed of headlines labeled positive or negative. For active market participants, its value lies in detecting when a ticker-specific narrative is accelerating, identifying the evidence behind that move, and separating meaningful attention from recycled noise. The difference matters most before a narrative becomes obvious in price action and volume.
Raw market information is abundant. Signal is not. A single large-cap name can attract hundreds of posts, dozens of articles, earnings commentary, analyst discussion, and broad sector references in a single session. Without structure, that data creates more monitoring work rather than a faster research process. A useful API turns that stream into a time-aware, explainable signal that can power screens, alerts, models, and internal dashboards.
What a Stock News and Sentiment Scoring API Should Measure
A sentiment score alone is incomplete. Language polarity may indicate that a headline is favorable, but it does not tell you whether the source is credible, whether the story is new, whether attention is expanding, or whether the market has already absorbed the narrative.
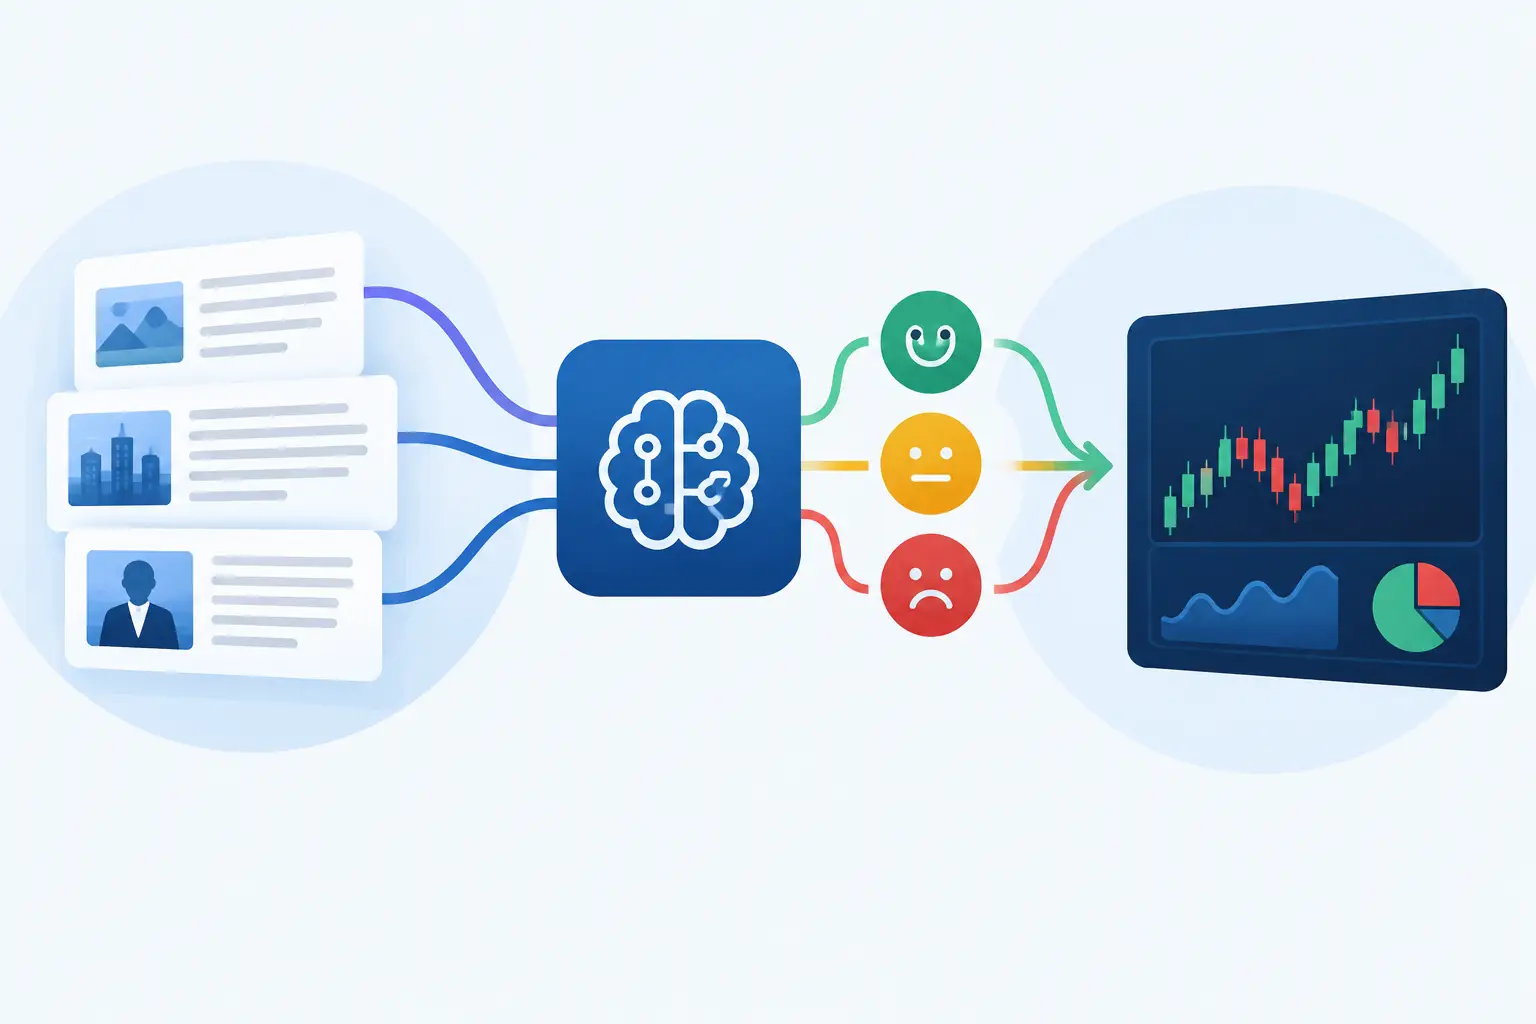
A stronger system evaluates several independent dimensions. News sentiment measures the directional framing of verified coverage around a company or event. Social sentiment tracks the directional tone of public conversation. Attention or momentum measures the rate at which mentions, articles, and engagement are changing. Technical context shows whether market behavior is confirming, ignoring, or contradicting the information flow.
These signals should remain distinct before they are combined. A surge in social attention may be meaningful, but it is not equivalent to a confirmed corporate development. Likewise, an earnings-related headline from an established publisher should not carry the same weight as a repetitive repost or an unverified claim. Treating every mention as equal is how noisy data becomes misleading data.
For a developer, this distinction creates better model inputs. For a trader, it creates a clearer view of why a ticker is appearing on a screen. The best output is not a black-box number. It is a score paired with evidence, timing, source quality, and component-level context.
The Anatomy of a Useful Sentiment Score
A scoring model should answer two questions: what is being said, and how much should it matter right now?
The first question requires entity-level language analysis. The system must determine which ticker a story actually concerns, distinguish the company from a sector peer mentioned in passing, and understand whether the language is directed at the company, its products, leadership, financial results, or broader industry conditions. Keyword matching alone will fail here, particularly for companies with common names, ambiguous tickers, or stories covering multiple issuers.
The second question requires weighting. High-quality scores typically incorporate source credibility, article recency, novelty, relevance, and attention velocity. A verified report covering new guidance has a different market profile than ten near-identical posts reacting to an old report. The score should recognize that difference.
Recency and Decay
Market narratives have a shelf life. A scoring API should apply time decay so that a two-hour-old catalyst influences the score more than a similar item from several days ago. The decay rate should not be fixed across every event type. Major filings, earnings releases, regulatory decisions, and material corporate announcements can remain relevant longer than a fleeting social burst.
This is where timestamps become essential. Developers need more than a current aggregate score. They need a history of the score, event times, and the underlying count of new evidence. That allows a model to detect inflections rather than simply rank the loudest names at a point in time.
Volume Is Not Momentum
High mention volume can reflect persistent popularity rather than a new shift. Momentum is the change in attention relative to a ticker's normal baseline. A company that usually receives little discussion and suddenly sees sustained verified coverage may have a more meaningful narrative change than a widely followed name with a routine increase in chatter.
Baseline-aware scoring is especially useful for scanning thousands of symbols. It helps surface outliers instead of rewarding names that are always noisy. For momentum workflows, the key event is often acceleration: sentiment is improving, verified coverage is increasing, and the rate of discussion is moving beyond normal levels.
Evidence Must Be Visible
Explainability is not a cosmetic feature. It is the control layer that prevents users from acting on a score they cannot audit. Each score should be traceable to the articles, social posts, timestamps, source types, and supporting metrics that contributed to it.
That transparency also helps users recognize failure cases. A high social score driven by a narrow cluster of repetitive posts requires different treatment than a high news score tied to several independent verified sources. Evidence feeds let researchers make that distinction quickly rather than trusting an aggregate blindly.
Why Separate News, Social, and Technical Signals
Combining every input into one number may look clean, but it can conceal the reason a ticker is moving through a research workflow. Independent scoring preserves the signal structure.
News may lead when a fresh company-specific event changes expectations. Social conversation may lead when retail attention or thematic interest is building before broad media coverage catches up. Technical indicators may provide context on trend, relative strength, volatility, and confirmation. None of these data sets is sufficient in isolation across every market condition.
Consider two tickers with the same overall sentiment score. One may have improving news sentiment, rising article velocity, and moderate social participation. The other may be driven entirely by a sudden spike in social posts while verified news remains unchanged. The aggregate may look similar, but the narratives are materially different. A good API makes those differences queryable.
This also prevents an overly optimistic interpretation of positive language. Sentiment measures tone and attention, not certainty. Corporate headlines can be optimistic while the market focuses on valuation, timing, guidance quality, or an unrelated macro factor. The score is a research trigger, not a substitute for judgment.
Building Practical API Workflows
The right implementation depends on whether the user is monitoring intraday shifts, managing a multi-week research process, or building a systematic model. In all cases, the API should make it easy to retrieve current state, historical changes, and evidence-level records.
For a real-time alerting workflow, teams can set conditions around a combination of score change, news momentum, source quality, and unusual social activity. The goal is not to alert on every positive mention. It is to flag a meaningful deviation from a ticker's recent behavior. Alerts should include the event details that triggered them, so the recipient can assess context without starting a separate search.
For screening, the API should support filters that combine independent dimensions. A user may want symbols with rising verified-news sentiment, expanding attention, and a favorable technical regime, while excluding names where the signal is based only on low-quality social activity. This approach produces a smaller, more defensible watchlist than sorting by raw mention count.
For model development, historical point-in-time data is critical. A backtest must use the information that was available at the time, not revised labels or future aggregate values. Store timestamps, component scores, source metadata, and score revisions. Without this discipline, an apparently strong model can be driven by look-ahead bias rather than real predictive value.
Sentimentick applies this framework by weighting verified news, social chatter, and technical indicators independently, then exposing the evidence behind the signal. That structure gives users flexibility: visual screening and alerts for fast research, or REST API access for custom analytics and systematic workflows.
Questions to Ask Before Choosing an API
Before integrating a stock news and sentiment scoring API, evaluate data quality before endpoint count. Broad coverage is useful, but breadth without entity accuracy or source controls can create false positives at scale.
Ask how the provider resolves tickers in multi-company stories, handles duplicate or syndicated content, and labels source type. Ask whether scores are historical and point-in-time, whether they update when new evidence arrives, and whether the response includes the records that produced the score. Also verify rate limits, latency, market-hours behavior, and schema consistency. A model cannot be reliable if its inputs change format without warning.
There is also a trade-off between simplicity and control. A single composite score is easy to deploy in a lightweight dashboard. Component scores and evidence records require more implementation work, but they let serious users calibrate thresholds, test assumptions, and create rules that match their own process. For most advanced workflows, control wins.
The edge does not come from having more headlines than everyone else. It comes from recognizing which narrative is gaining credible momentum, seeing why it matters, and having the data structure to act on that research faster.