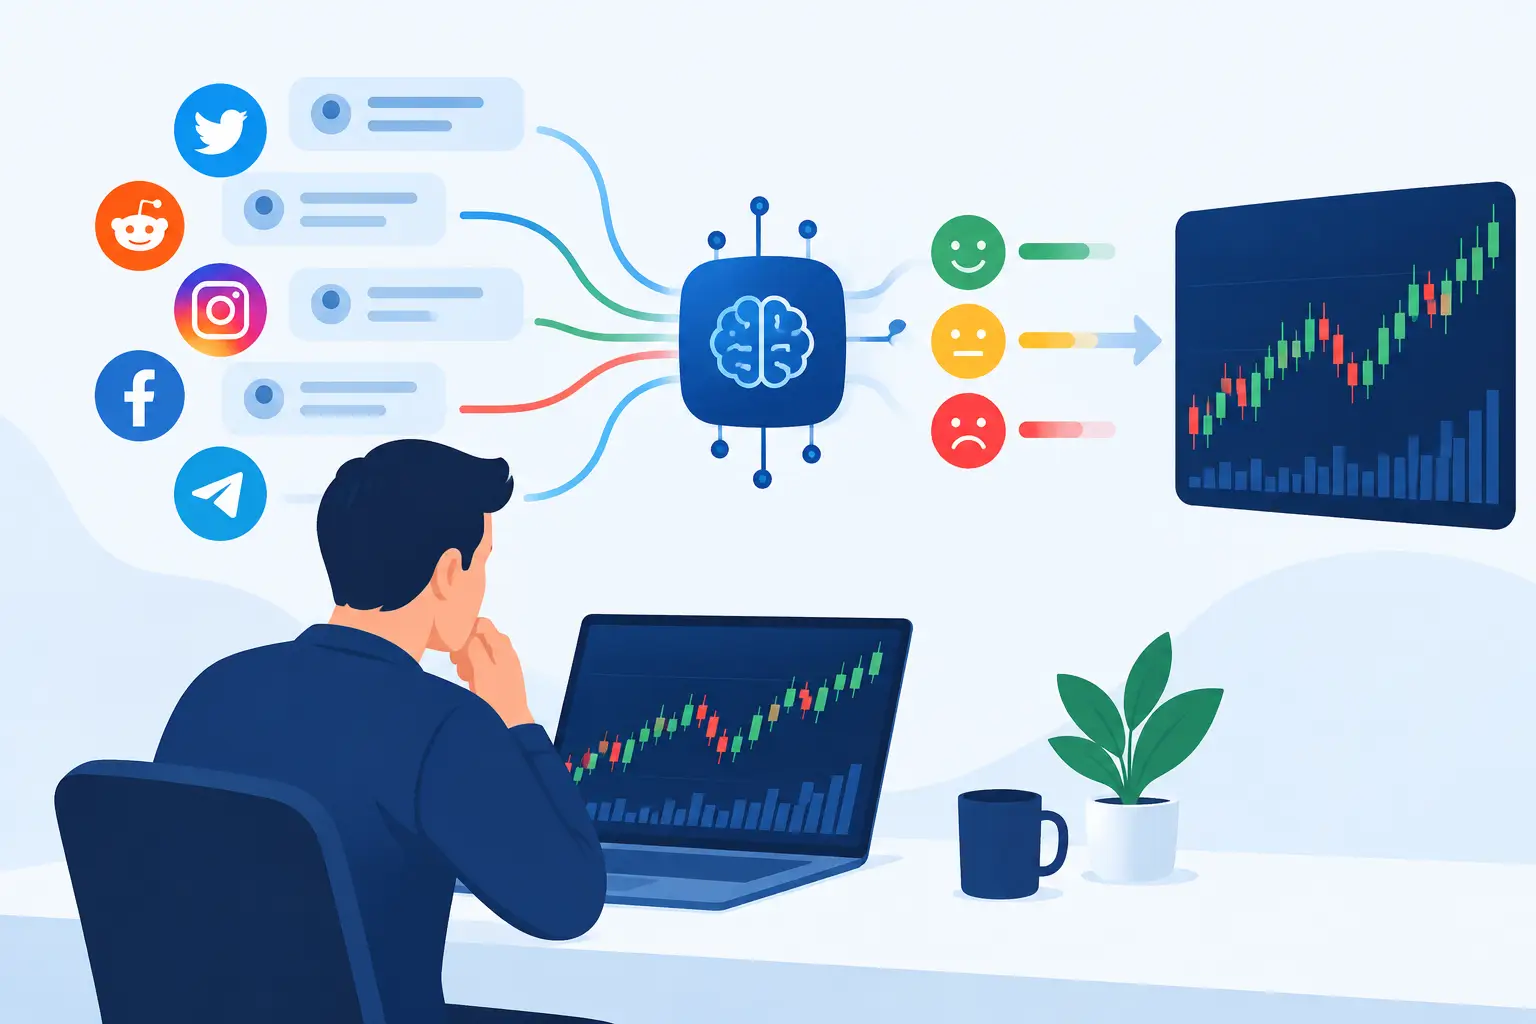
A social media sentiment analysis API is not valuable because it tells you whether the internet feels positive or negative. It is valuable when it shows where attention is concentrating, which tickers are gaining conviction, and whether a narrative is accelerating before the market fully reflects it in price and volume.
For active market participants, that distinction matters. A viral post can create plenty of noise without creating a tradable market narrative. A high-quality API turns raw conversation into structured, ticker-level intelligence that can be ranked, monitored, tested, and combined with the rest of a research workflow.
What a Social Media Sentiment Analysis API Should Deliver
At its core, a social media sentiment analysis API collects public conversation, identifies the assets being discussed, and assigns meaning to that activity. The baseline output is usually a sentiment label or score. For market use, that is only the starting point.
A useful data feed should preserve the context behind the score. You need to know whether sentiment is moving, how broad the discussion is, whether mentions are concentrated in a handful of accounts, and how the current reading compares with the ticker's own historical baseline. Ten thousand neutral posts are not automatically more meaningful than a smaller, fast-rising cluster of high-conviction commentary tied to a specific catalyst.
The API should also resolve ticker ambiguity. Symbols can overlap with ordinary words, abbreviations, and unrelated tags. Without entity resolution, a feed can assign irrelevant conversation to a security and create false signals. This is especially problematic for short tickers and names that appear frequently outside financial discussion.
For traders and systematic researchers, the best endpoint is not a generic social score. It is a time-stamped, evidence-backed view of attention and sentiment at the ticker level.
Why Raw Sentiment Scores Miss the Signal
Sentiment is a directional input, not a verdict. A strongly positive score can reflect broad optimism, promotional chatter, a reaction to verified news, or a crowded narrative nearing exhaustion. The same numeric value can mean very different things depending on velocity, source quality, and market context.
That is why a simple positive-to-negative ratio is rarely enough. The more useful question is: what changed? If a stock normally receives limited discussion and its mention rate suddenly expands alongside improving sentiment, that shift deserves attention. If it already dominates conversation every day, another surge in mentions may be less informative.
Recency changes the interpretation as well. Social conversation moves in minutes, not quarterly reporting cycles. An API that updates too slowly may describe a narrative after the market has already processed it. At the same time, a feed optimized only for speed can overreact to fleeting posts. The edge comes from measuring acceleration while retaining enough history to separate a genuine regime change from a short-lived spike.
Source quality is the other major trade-off. Broad coverage captures emerging chatter earlier, but it also introduces more spam, repetition, and low-information posts. Tighter filtering improves signal quality but can miss narratives before they reach established accounts. There is no universal setting. A momentum scanner may tolerate more early noise than a longer-horizon research model, provided its downstream filters are disciplined.
The Data Fields That Matter in Practice
A developer-ready social sentiment feed needs more than a single daily score. At minimum, a market-focused response should make it possible to evaluate sentiment, attention, momentum, and evidence without reconstructing the dataset from scratch.
The most actionable fields typically include:
- Timestamped sentiment scores at intraday and historical intervals
- Mention volume and mention velocity relative to a ticker baseline
- Bullish, bearish, and neutral conversation splits
- Source metadata and author or post-quality signals where available
- Ticker confidence, entity-resolution status, and supporting post or narrative evidence
A normalized score matters because raw mention counts favor widely followed names. A ticker receiving 200 mentions may be unremarkable for one mega-cap and highly unusual for a less-covered stock. Baseline-relative metrics make those differences visible.
Evidence matters just as much. Black-box outputs are hard to trust when a score abruptly changes. A usable API should let the researcher inspect the underlying narrative: what topics are appearing, which posts or sources drove the move, and whether the language reflects a real catalyst or recycled speculation. Transparent evidence feeds reduce the time spent chasing misleading alerts.
Build a Signal Stack, Not a Sentiment-Only Model
Social data works best as one independent layer of market intelligence. Treating it as a standalone prediction engine creates a familiar failure mode: high attention is mistaken for high-quality information.
A stronger workflow evaluates social sentiment beside verified news momentum and technical context. Social conversation can flag a developing narrative. Verified news can confirm whether there is a credible catalyst. Technical data can show whether the market is responding, consolidating, or moving against the story. Each layer answers a different question.
For example, an increase in bullish discussion without any verified catalyst may still be worth monitoring, particularly if attention velocity is abnormal. But it should not carry the same weight as a sentiment shift that appears alongside a material news event and expanding market participation. Conversely, a news release with little social traction may be less likely to develop into a sustained retail attention cycle.
Independent weighting is critical here. If social posts, news articles, and price commentary all repeat the same underlying event, a system can accidentally count one catalyst three times. Separate inputs with transparent weighting make the model easier to audit and less vulnerable to narrative echo chambers.
Practical API Workflows for Traders and Developers
The most direct use case is an outlier screener. Query the API for tickers with rising mention velocity, improving sentiment delta, and a volume threshold that is unusual relative to their own recent history. Then layer in price, liquidity, sector, or news conditions based on the workflow. The goal is not to chase every spike. It is to reduce a market-wide universe to a manageable set of changing narratives.
A second workflow is conviction tracking. Instead of checking a watchlist manually, maintain rolling sentiment and attention baselines for the tickers that matter to your research. Trigger an alert when a score changes materially, when negative discussion accelerates, or when engagement shifts from isolated commentary to broad participation. Alerts should be selective. If every mention creates a notification, the system has recreated the information overload it was supposed to solve.
Developers can also use the feed as a feature layer in custom models. Sentiment level, sentiment change, mention velocity, dispersion across sources, and persistence over several windows can each become separate variables. Do not collapse them into one composite score too early. Preserving feature-level data lets you test what actually adds explanatory value for a given holding period or universe.
Sentimentick applies this same principle by separating social chatter, verified news momentum, and technical indicators rather than presenting internet activity as a single market truth. For researchers, that structure makes it easier to identify why an alert fired and decide whether the signal fits the current setup.
How to Evaluate API Quality Before Integration
API documentation can make almost any dataset sound comprehensive. Evaluation requires asking operational questions. What is the update cadence? Which sources are included? How are deleted posts, spam, reposts, bot-like activity, and duplicate content handled? Can you retrieve historical data with consistent methodology, or only a live stream?
Coverage should be tested across the securities you actually follow. A feed that performs well on the most discussed large-cap names may have weak resolution or sparse data for small and mid-cap tickers. This does not automatically disqualify the provider. It simply determines where the data should carry less weight.
Historical consistency is essential for backtesting. If the vendor changes its model, sources, or score calibration, old and new readings may not be directly comparable. Ask whether the API provides model versioning, data revisions, and clear definitions for each field. A clean-looking time series is not useful if its construction shifts without notice.
Reliability also has a practical meaning: can your systems handle rate limits, delayed records, and missing intervals? A production workflow should define fallbacks rather than assuming the feed will always be complete. Cache responses where appropriate, log the raw payloads that generated alerts, and monitor distribution changes in the data. Sudden changes in average sentiment or mention volume may indicate a genuine market shift, but they can also signal a collection or classification issue.
Turn Data Into Faster Research Decisions
The point of a social media sentiment analysis API is not to automate conviction. It is to direct attention toward the market narratives changing fastest, while giving you enough evidence to judge whether they deserve further research.
Start with a narrow universe and a clear hypothesis. Measure whether sentiment acceleration improves the speed or quality of your research process when paired with news and technical context. Keep the raw fields, inspect the evidence behind anomalies, and tune thresholds to the behavior of the assets you track. The most valuable signal is often not the loudest conversation, but the early, measurable shift that your existing workflow would have missed.