Price data is easy to retrieve. Market context is harder. A financial data API for developers becomes valuable when it helps a model distinguish routine ticker movement from a developing narrative that may be drawing real attention.
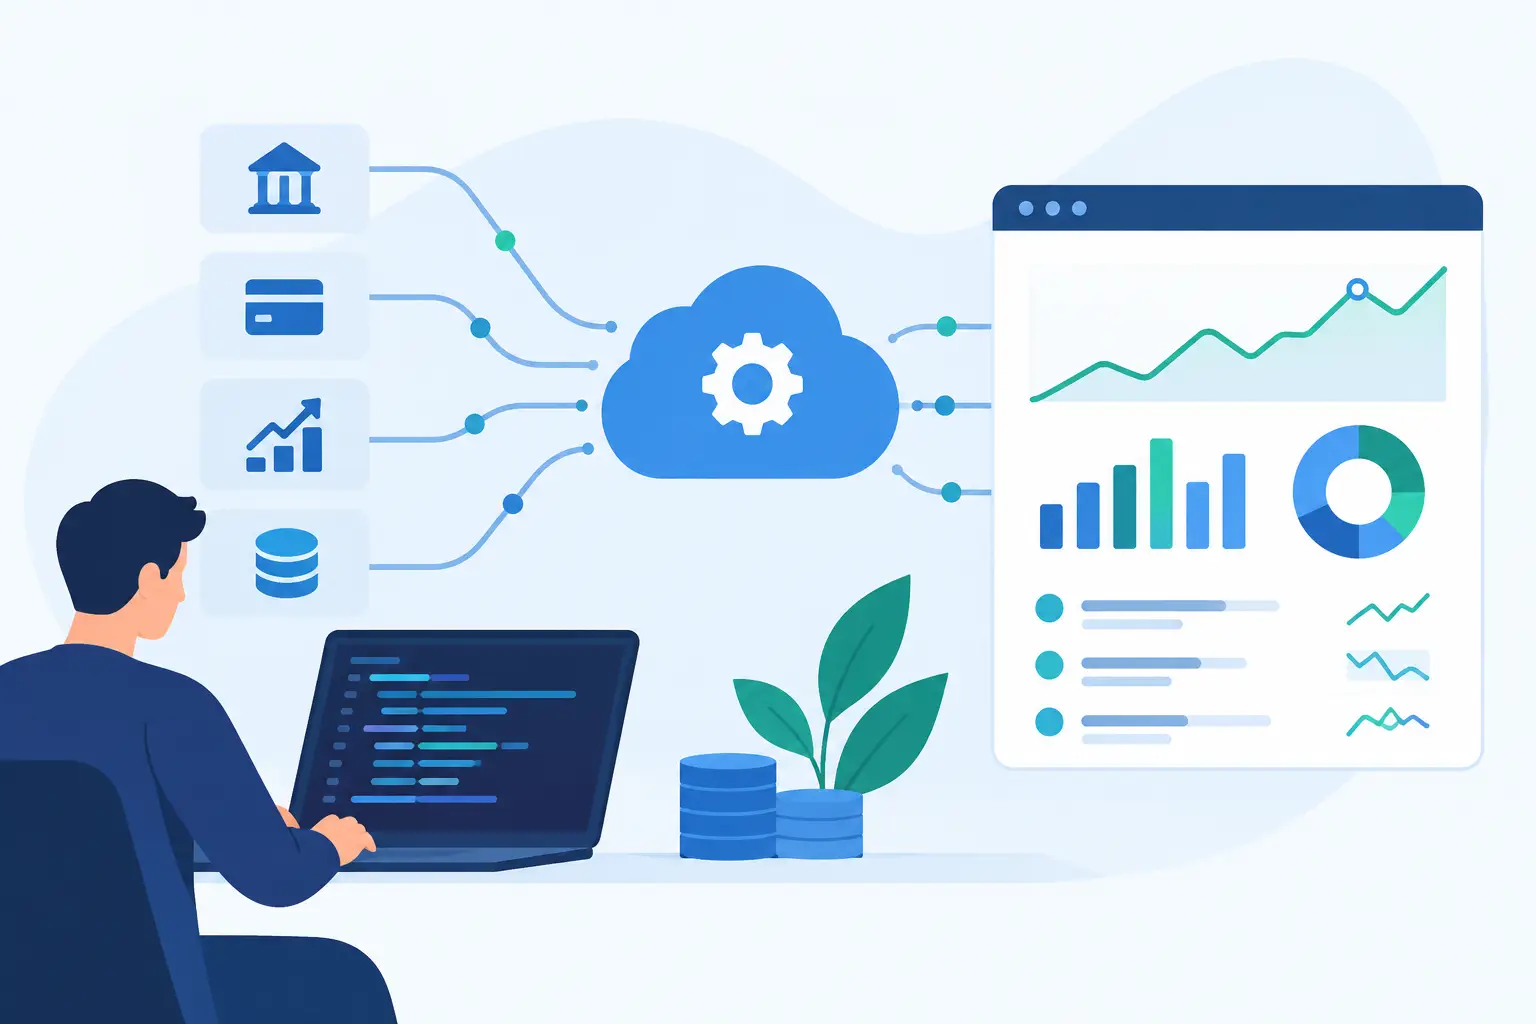
For systematic traders, quantitative hobbyists, and fintech teams, the objective is not to collect the largest possible dataset. It is to build a dependable signal pipeline: one that captures changing attention, validates the source of that attention, adds technical context, and returns results fast enough to support research workflows and alerts.
What Developers Actually Need From Financial Data
A closing price, intraday bar, and basic company profile can support a chart. They do not explain why a ticker is suddenly appearing across news cycles, social conversations, and watchlists. Developers building market intelligence tools need data that answers a more useful question: what is changing, and how credible is the change?
That requires multiple data dimensions that remain distinct. Verified news momentum measures whether reputable coverage is accelerating. Social sentiment measures whether retail attention is expanding or fading. Technical indicators establish the market structure around the discussion. Combining them can be useful, but collapsing them into one unexplained score removes the evidence needed to evaluate a signal.
The best API design preserves the underlying components. A strategy may weight news more heavily during earnings season, while a short-horizon attention monitor may prioritize unusual social velocity. There is no universal weighting model. Developers need the freedom to test assumptions, inspect inputs, and revise logic as market conditions change.
Signal quality matters more than feed volume
High-volume data can create a false sense of coverage. If an API captures every mention without identifying duplicates, low-quality sources, stale posts, or unrelated ticker references, the output becomes another form of noise. A useful financial data layer applies filtering before the data reaches the model.
This does not mean every signal should be aggressively sanitized. Early market narratives are often messy. The right balance is transparent evidence: enough curation to reduce manipulation and repetition, with source-level detail that lets developers apply their own confidence thresholds. A feed that shows why a score moved is more useful than a black-box label.
How to Evaluate a Financial Data API for Developers
The evaluation process should begin with the application, not the endpoint catalog. An alerting engine, a portfolio research dashboard, and a backtesting environment each have different tolerance for latency, revision history, and data granularity.
For a real-time ticker monitor, look closely at update cadence and timestamp consistency. It is not enough for records to have a timestamp. You need to know whether it reflects publication time, ingestion time, calculation time, or the latest update. Those differences affect alert ordering and historical analysis.
For historical research, schema stability and point-in-time integrity matter more. If sentiment values are recalculated later without a versioning strategy, a backtest can quietly incorporate information that was unavailable at the time. That produces cleaner-looking results and weaker live performance. Historical endpoints should make it possible to understand what the system knew at a given moment.
For product teams, coverage and normalization deserve equal scrutiny. Ticker symbols change, companies merge, and similarly named securities can create mapping errors. A clean security identifier strategy prevents subtle failures in dashboards and automated workflows.
Four questions are worth asking before integrating any provider:
- Can you inspect the evidence behind a news or sentiment score?
- Are real-time and historical records clearly timestamped and consistent?
- Does the API separate sentiment, news momentum, and technical context instead of blending them without explanation?
- Can the data be filtered by ticker, source quality, time window, and signal threshold?
These questions expose whether the API is built for serious analysis or simply for displaying market widgets.
Build Around Events, Not Constant Polling
Many early API implementations start by polling every ticker on a fixed schedule. That approach is simple, but it scales poorly and wastes attention. Most symbols are inactive most of the time. The objective is to detect meaningful change, not repeatedly confirm that nothing happened.
A stronger architecture uses a watchlist or universe definition, then applies event thresholds. For example, a workflow can flag symbols when news momentum rises materially over a rolling baseline, when social mention velocity changes sharply, or when sentiment shifts while a technical condition is already present. The threshold should reflect the intended workflow, not a generic market-wide setting.
Store raw responses alongside normalized features during development. Raw records make it easier to investigate a surprising alert, identify parsing issues, and revise feature engineering without losing the original evidence. Normalized tables then support fast queries for dashboards, screening, and model inputs.
Rate limits also shape architecture. Batch requests where the API supports them, cache slow-changing reference data, and reserve high-frequency calls for active symbols. A rate limit is not merely an operational constraint. It forces discipline around what the system truly needs to know right now.
Treat alerts as research triggers
An alert should not pretend to be a final market conclusion. Its job is to direct attention to an unusual condition with enough context to assess it quickly.
A useful alert payload includes the ticker, event time, current signal values, recent change, supporting evidence count, and a compact view of relevant technical context. A vague message such as “sentiment is positive” gives the recipient almost nothing to investigate. An alert showing that verified news momentum accelerated while social discussion expanded and price structure changed gives the researcher a starting point.
This distinction is critical for automated systems as well. Models should receive features with lineage and confidence, not unsupported declarations. When conditions change, developers can then identify which input moved and whether that movement was driven by news, conversation, or market structure.
Use Independent Signals to Reduce False Confidence
Correlated data sources can create false confidence. Ten posts repeating the same headline are not ten independent confirmations. A burst of social activity may be organic, coordinated, reactive to news, or disconnected from verified information. Technical movement can confirm attention, but it can also reflect broad sector activity rather than a company-specific development.
Independent scoring helps manage this problem. Keep news momentum, social sentiment, and technical indicators as separate features first. Then test combinations based on the exact question being asked.
A narrative-detection model may require a minimum level of verified coverage before social activity influences its ranking. A market scanner may identify unusual attention first, then use technical filters to prioritize symbols worth reviewing. A portfolio research tool may track whether a long-running narrative is strengthening or losing support over time. Each design uses the same data categories differently because the workflow is different.
Sentimentick is built around this separation: verified news, social chatter, and technical analysis are independently weighted, with evidence feeds that let users and developers inspect the signal rather than trust a headline score blindly.
Operational Details That Protect Data Quality
Market data systems fail in ordinary ways: delayed jobs, duplicate events, symbol mapping errors, missing fields, and occasional source outages. Treat these as expected conditions rather than edge cases.
Use idempotent ingestion so replayed events do not inflate counts. Track the last successful cursor or timestamp per endpoint. Monitor freshness separately from availability, because an endpoint can return a successful response while serving stale records. When data is incomplete, expose that state to downstream users instead of silently filling gaps with old values.
It also helps to define a clear data contract internally. Document each field, its units, its possible null states, its update frequency, and whether it can be revised. This prevents a common mistake: treating a directional sentiment metric as if it were a probability, or interpreting a count-based momentum score as a measure of market conviction.
Build for Explainability From the Start
The fastest way to lose trust in a market tool is to surface a surprising result with no path to verify it. Explainability is not decoration for an API product. It is a core performance feature.
When an alert fires or a screener ranks a ticker, retain the inputs that produced the result. Show the time window, the score changes, the evidence sources, and the conditions that passed the filter. This makes the output easier to audit, improves debugging, and helps users develop better rules over time.
The edge is rarely a single data point. It comes from recognizing when independent signals begin to align, while still being able to see the evidence underneath. Build your financial data pipeline to preserve that judgment. Speed gets attention; transparent signal intelligence helps keep it.